Your own GPU server, your private AI models, running your One
From$4,000a monthNo setup or maintenance fees
Your server
Power for your private models.
Text and speech models every employee’s bots can use. Image models, if you want them.

Our recommendation for enterprise AI
Larger models and memory-heavy work
Large-scale training and inference
Configuration and price are matched to your workload.
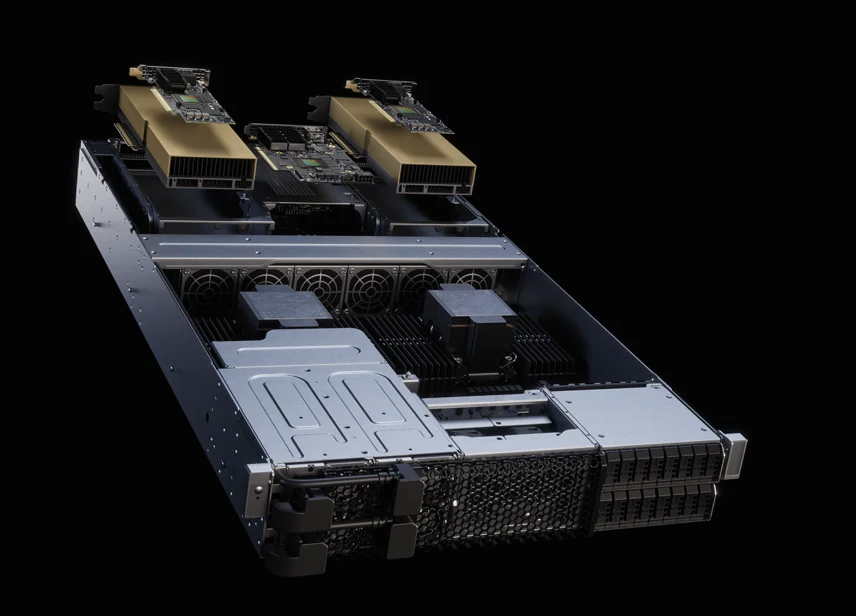
Built to run your whole One.
Enterprise processors and DDR5 ECC memory keep the app, database and bots’ computers working together.
- AMD EPYC or Intel Xeon
- DDR5 ECC memory
- Browsers, files and scheduled work
Configuration and price are matched to your workload.
Your work. Right here.
Fast NVMe storage for the knowledge your company builds, and the models that learn from it.
- Libraries, files and conversations
- Your fine-tuned model
- Capacity and backup policy agreed with you
Configuration and price are matched to your workload.
Connected on your terms.
Your people reach One. Your models stay private. Outside connections follow the policy you choose.
- Private access to your deployment
- NVIDIA ConnectX networking options
- Approved apps, calls and web access
Configuration and price are matched to your workload.
Choose your models
We host the open models you pick, as long as they fit your server.
Options to assess together. Hardware, commercial rights and training support vary by model.
Your model knows your work
The model can* be trained on your same server hardware.
Made from your work.
Made for you.
The model it produces is yours, under your agreement with us and the licence of the open model it started from.
*Model size, training method and available memory determine what fits. We agree a training window and how serving continues.
Your serverServing your models
You choose what goes in.
We use the data your policy allows, and nothing else.
- Product specifications
- Care and repair guides
- Answered customer emailsCustomer names removed
- Employee recordsYour policy leaves these out
Turned into examples.
We turn that data into training examples, following the same policy.
- Question
- Can the Arden table go outside?
- Answer
- No. Arden's oiled oak is made for indoors. For outside, the Arden Teak edition is built for it.
Trained on your server.
When the model and training method fit, we use your existing GPUs. We agree capacity and a training window with you.
Checked against your answers.
We ask it questions your team has already answered, next to the model you use now. You decide if it goes live.
Can the Arden table go outside?
Most solid wood tables can go outside if they're sealed and kept covered.
No. Arden's oiled oak is made for indoors. For outside, the Arden Teak edition is built for it.
In use by everyone's bots.
Once you say yes, it runs on your server beside your other models, and every employee's bots can use it.
Yours, under your agreement with us and the open model's licence.
Their own One. Your oversight.
Manage your people
Invite employees, change access and deactivate accounts when someone leaves.
Set the boundaries
Choose who can join, which domains are allowed and which models your people can use.
Keep each One personal
Everyone has their own crew, spaces, Library and memory. Administration doesn’t turn them into a shared account.
You’re in control.
People & access
Select a role or pause someone’s access.
Who can join
Verified domainsPeople on your allowed domains can join.
Models for your people
Private deploymentEveryday work
Your company’s knowledge
Private speech
Choose which private models your employees can use.
Choose what goes out
- Stays on your server
- The contracts, the model's work and the draft.
- Goes out
- Nothing.
Your private deployment follows the policy we agree with you. External services are optional; approved connections receive only their task inputs.
Data boundaries on our other plansWe run it. You use it.
Setup and upkeep are part of the price: there are no setup or maintenance fees.
What we do
- Set up your server, One and your models
- Keep the server running and One up to date
- Host the models you choose, and test stronger ones for you
- Fine-tune models on your data, when you ask
- Build the custom work we agree
What you do
- Choose your models, and say yes before one changes
- Set the data policy for fine-tuning
- Decide who can sign in
- Approve any outside providers and apps
Changes to One, for your company.
When your company needs something One doesn't do, such as a connector to an internal system or a workflow of your own, tell us.
- 01
Scope
We agree what it does, whether it's realistic, and the plan.
- 02
Build
We build it into your One.
- 03
Maintain
We keep it working as One is updated.
If something is beyond what we can build well, we'll tell you before we start.
Discuss a custom requirementHow it starts.
From a first conversation to your company signing in.
Talk to us about your data and models
Tell us which work matters, which models you want and what your data policy allows. We agree the server and the price with you.
We set up your server
We install One and your models on it, and connect the providers you choose.
Your company signs in
People sign in with their work email and get their own crew. We run the server from there.
From$4,000a month
No setup or maintenance fees
- A GPU server for your company alone
- One for everyone at your company
- The open text, voice and image models you choose
- Fine-tuning on your data, when you ask
- Setup, upkeep and model updates by Lughlabs
- Custom work, scoped with you
The server and the final price are agreed with you. Carriers and hosted providers you connect bill you directly.
Everything in Teams, on your own server.
The phone line, team chats, spaces, bot groups and the Architect run on your server too.
See One for TeamsWhat IT and security ask us.
Do you train on our data?
Only when you ask us to fine-tune a model for you, and only on the data your policy allows. Otherwise, we don't use your content to train models. Terms of Service
Who owns the fine-tuned model?
You do, as your agreement with us sets out. It starts from an open model that has a licence of its own, and those terms carry over to the fine-tuned model. We go through them with you before training.
Which models can we run?
Language, speech, image and specialist GPU models that fit your hardware and permitted use. We agree deployment, integration and any fine-tuning with you. Larger models may need a larger configuration. Each model card links to its publisher and licence. Models
What leaves the server?
Your private model requests, Libraries, files and memory stay on your server. Approved outside services receive the inputs their tasks need: call audio for a carrier, updates for connected apps, queries for search, and addresses for sign-in mail. If you approve an external model, voice or image provider, its task inputs go there too. We agree these boundaries for your deployment before setup. Trust & deployment
Where does the server run?
We agree where it runs, and how it's kept apart, with you during setup. Deployment
Can employees share a workspace?
Each employee has their own account, crew, spaces and Library. Their bots can work together through connected team chats with approval. If you need shared workflows or additional controls, we scope them with your enterprise deployment.
What does it cost?
From $4,000 a month, with no setup or maintenance fees. The final price depends on the server your work needs. Carriers and hosted providers you connect bill you directly. Pricing
What can you build for us?
Changes to One that your company needs, such as a connector to an internal system or a workflow of your own. We agree the scope, and whether it's realistic, before we start. Discuss a custom requirement